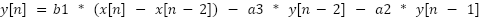
Digital speech vocoder
[Fall 2023] For our final project we built a digital vocoder allowing one to talk into a microphone and hear their transformed speech through a speaker. The main idea is to use human speech to modulate a synthesized carrier signal, which produces output speech that says what you are saying, but sounds nothing like you. For our project we chose and tested a handful of carrier signals, but spent most time using a sawtooth wave carrier because it produces the most electronic-sounding output. This m
- Suitable forB.Tech/B.E Embedded Systems students
- Build time4-6 weeks
- LevelBeginner
- Available atAjvika Labs, Kakinada
About this project
Charlie Mueller - cmm478
Schuyler Seyram - ses398
Project Introduction
For our final project we built a digital vocoder allowing one to talk into a microphone and hear their transformed speech through a speaker. The main idea is to use human speech to modulate a synthesized carrier signal, which produces output speech that says what you are saying, but sounds nothing like you. For our project we chose and tested a handful of carrier signals, but spent most time using a sawtooth wave carrier because it produces the most electronic-sounding output. This made our vocoder sound more like an autotuner, which we found interesting because we wanted to produce output that sounded robotic. We were also able to allow the user to change the pitch of the transformed output manually, either raising it or lowering it. This was an important feature we wanted to add because we wanted our vocoder to be similar to an actual vocoder one could purchase, where a user can change the voice output at a bunch of different pitches and sounds, not just one. Overall, we finished with allowing the user to change which carrier signal was being used to synthesize the output, and the pitch of the output. This made our project more interactive, intuitive, easy to play with, and provided a wide range of ways one could disguise, transform, and change their voice.
High Level Design
Rationale and Sources
We initially spent a significant amount of time trying to decide what broad topic to develop our project in. The possibilities were overwhelming but we knew we wanted to do something with that involved data transfer or augmentation. Signal processing was a topic we had relatively little experience with, and we both were particularly fascinated by the bird chirp synthesis lab, so we decided to select an audio-based project. One of us was particularly interested in the range of human voice frequency we could capture and process with the Pico as compared to traditional laptops coupled with audio synthesis software. We also wanted our project to be something that people could actually use and make it as practical as possible, so for all these reasons we landed on a vocoder. We browsed past student projects and found that another group tried a vocoder in the past but couldn’t get it fully working due to the PIC32 processor not being able to run at a high enough frequency. We looked at the timing specs and observed that the RP2040 is clocked at over double a frequency from the PIC32 (125 MHz vs 50 MHz). With this gain in speed, along with overclocking and the multi core capabilities of the RP2040, we figured we could build a powerful vocoder that could fully transfer and manipulate speech.
Background Math
We took samples from the microphone input using the Pico’s ADC. We chose a sampling rate of 8kHz. So we took ]\ a continuous time signal (human speech), and made it discrete by taking samples at intervals of 125 microseconds. Given our discrete set of samples, we reconstructed a continuous time signal by outputting samples to the DAC. The Nyquist Rate tells us how fast we need to sample a signal with a given frequency to collect a set of samples that uniquely determines the original signal given our sampling rate. More precisely, if we try to sample a signal lower than its Nyquist Rate, then the set of samples we obtain could have been obtained by sampling other signals with different frequencies. This is called aliasing, and it would cause our continuous output signal to not capture the higher frequency components of the input signal. This is because these higher frequencies above the Nyquist Rate would be clipped down to lower frequencies that have the same samples at that sampling rate. We wanted to capture as much of human speech as possible, and even though speech has most of its frequency content around 100-400 Hz, we wanted to be able to capture up to 3.5 kHz which includes singing. The Nyquist Rate is two times the frequency of the input signal, so to uniquely capture signals up to 3.5 kHz, we needed to sample at a rate of at least 7 kHz. Our sampling rate of 8 kHz was then definitely sufficient to sample and reconstruct all the frequency content of the speech.
As described in the next section, the way a vocoder works is by sampling the speech and passing the samples through a series of bandpass filters each covering a different frequency range, allowing us to deconstruct the speech and carrier signals by their frequency content. We chose to use second order butterworth bandpass filters, which use the following filter equation:
This generates the current output y[n] given the current input x[n], past input x[n-2], past outputs y[n-2] and y[n-1], and coefficients b1, a2, and a3. The coefficients are calculated based on the cutoff frequencies of the bandpass filter. In our implementation we did not use arrays, which we will explain in the program design section.
The final part of the math we needed to consider was how to amplitude modulate the carrier signal. We pass the speech input and carrier signal through a set of bandpass filters, getting filtered samples of each. We need to impose the envelope of the filtered speech at each frequency onto the carrier sample. We accomplished this by first rectifying both filtered samples, and then low passing each to reduce noise. This gave us the envelope, or peak shape of both signals. Then, we could take the ratio of the speech envelope to the carrier envelope, and multiply this by the filtered carrier sample, forcing the carrier sample to take the same shape as the speech.
Logical Structure
A vocoder works by analyzing the frequency content of signals. We used an AdaFruit microphone connected
to the Pico’s
ADC to get the speech. This microphone was powerful and simple to use as it required little setup. We sampled the ADC input at a rate of 8kHz to get our speech input. Each speech sample is then passed through a number of bandpass filters with different frequency ranges from 20 - 3999 Hz covering all of the frequencies we want to be able to capture. We also needed to pass carrier signal samples through the bandpass filters as well. However, one important fact that Hunter helped us with during the lab is that we needed the same number of carrier signal synthesizers as bandpass filters. For each filter, we send a carrier signal sample generated at the center frequency of that filter. So for 18 bandpass filters total, we synthesized 18 waves from the carrier signal, each one at the center frequency of the corresponding bandpass filter. So while the same speech sample is passed through all 18 bandpass filters, a separate carrier sample is passed through each filter. Then, the filtered carrier and speech sample are rectified and low-passed so we can find the peak of each with minimal noise. So for each frequency range (out of 18), we have the frequency content of the speech in that range, and a filtered carrier sample in that range. The ratio of the low-passed speech to low-passed carrier sample is then multiplied onto the filtered carrier sample, shaping the peak of the carrier sample for that frequency range to be the same as that of the speech’s frequency content in that range. Then, all 18 modulated carrier samples are summed up, and the resulting output is sent to the DAC.
Different carrier signals produce different-sounding outputs, so we created multiple carrier signals including: sawtooth wave, triangle wave, and white-noise. The user can use the keypad to select which carrier signal to use, and can also use the keypad to increase or decrease the pitch of the synthesized output. These instructions were displayed on the VGA screen to create a helpful interface for the user to know what they could do with the vocoder.
Program Design
ISR Organization
We set up an ISR on core 0 of the Pico to fire every 125 microseconds, or 8kHz. In the ISR routine we sampled a value from the ADC using adc_read(). We also kept a global variable containing the next output to be sent to the DAC. This is because we used a protothread to do all of the vocoder computations. We wanted output samples to be sent to the DAC immediately following sampling an input, rather than doing the computation inside of the ISR, which would send an output sample roughly 90 microseconds after taking an input sample. So, we used another global variable to indicate that there was an ADC sample ready to be used. The vocoder thread would wait until this variable was set, and when it was, the thread would then process the input sample using the filtering scheme mentioned above, and store the output in the global variable for the DAC output. The vocoder thread ran on core 0 as well. However, we still needed all of our computations to be less than 125 microseconds, otherwise the output sample from a given input wouldn’t be ready by the next time the interrupt fired, and we would be sending multiple copies of the same output. This had the effect of making the output speech delayed and a lot slower, which was a small problem we ran into.
Fixed Point Representation
The ADC and DAC both operate on 12 bit values. For the filter implementations, we needed at least 5 decimal bits of resolution as specified by Bruce in his DSP page, linked below and in the Appendix. He also helped us discover that 5 decimal bits corresponds to 16 fractional bits. It couldn’t hurt to get as much resolution as possible, so for our fixed point implementation we used 1 sign bit, 12 integer bits (to handle ADC/DAC data), and 19 fractional bits. We could use fixed point methods to then convert our ADC sample to fixed point for computation. To convert our output from fixed point to a 12-bit int for the DAC, we had to do something slightly more complicated because all of our computations handle negative values, but the DAC output cannot be negative. Instead of right-shifting by 19 we right shifted by 20, leaving a number between -2048 an
Technologies used
Hardware components
- RP2040
- PIC32
- microphone
- speaker
- DAC
- ADC
Software & tools
- C
- Arduino IDE
Project demo video
What you get
- Working project / hardware kit, tested before delivery
- Complete source code with explanation
- Project demo and guidance for your viva
- Project report, PPT and IEEE paper support (on request)
Related Embedded Systems projects

Gas Leakage Detector Using Arduino
A budget-friendly LPG gas leak detector built with an Arduino and MQ-5 gas sensor, triggering a buzzer and LED when unsafe gas levels are de...
View project
Simple Alarm System
A beginner-friendly home alarm with PIR motion sensing, keypad PIN entry, and separate entry/exit timing delays, built to be easy to expand.
View project
Ultrasonic Sensor Project with Arduino UNO Q
A beginner-friendly first Arduino UNO Q project: a servo-swept ultrasonic sensor that renders a live sweeping radar display in a web browser...
View project
3D Audio Localization
[Fall 2025] We designed a real-time embedded system that localizes sound sources in three dimensions and visualizes them live using a four-m...
View project